Reserve NVIDIA Vera Rubin NVL72 Capacity
Reserve full NVIDIA Vera Rubin NVL72 rack-scale systems to secure capacity for trillion-parameter AI workloads.
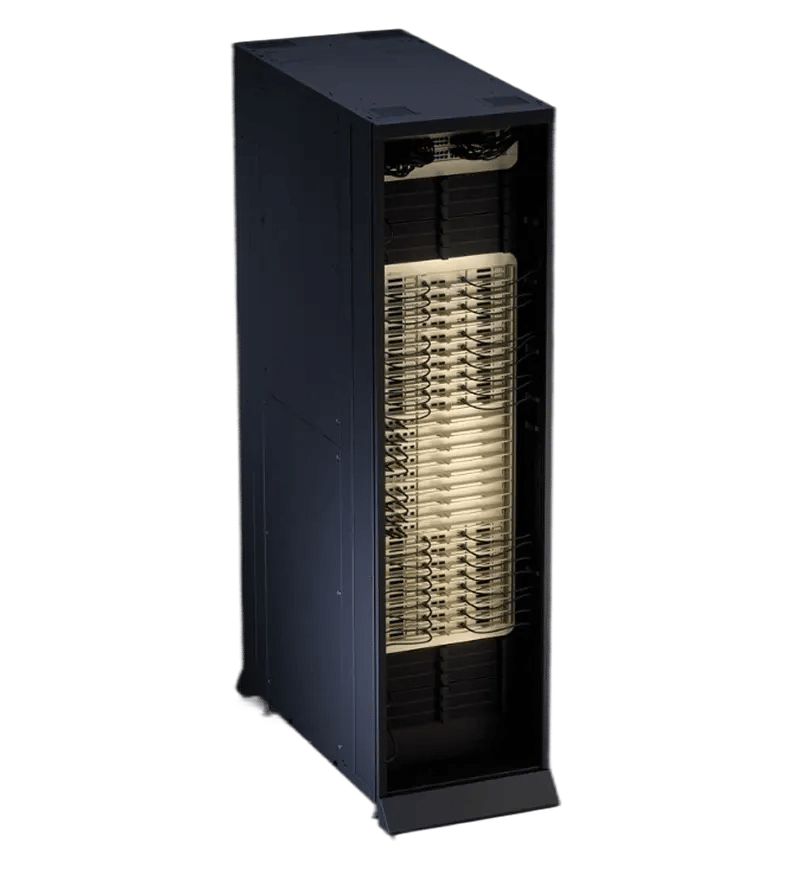
Why Reserve NVIDIA Vera Rubin NVL72 on Hyperstack
Guaranteed Access to Next-Gen Compute
Demand for the NVIDIA Vera Rubin NVL72 is expected to exceed supply. Reservations ensure your workloads are not delayed.
Lower Cost at Scale
Leverage NVIDIA Vera Rubin specs to achieve up to 1/4th training compute requirements and 1/10th inference cost for long-running workloads.
Priority Deployment and Allocation
Reserved users receive early access to the NVIDIA Vera Rubin NVL72, reducing time-to-deployment for critical AI infrastructure.
Transparent Usage and Billing
Track infrastructure usage, costs and allocation clearly through Hyperstack with full visibility across your deployments.
Priority Engineering Support
Work directly with experts experienced in large-scale AI systems, distributed GPU workloads and performance optimisation.
Why Teams Choose NVIDIA Vera Rubin NVL72 on Hyperstack
Compute Performance
Up to 3,600 PFLOPS NVFP4 inference performance delivers ultra-fast training and high-throughput inference.
Massive Memory and Bandwidth
20.7 TB HBM4 memory with 1,580 TB/s bandwidth removes bottlenecks in large-scale AI training and inference workflows.
Rack-Scale GPU Architecture
The Vera Rubin NVIDIA GPU scales across 72 CPUs with NVLink 6 for seamless multi-GPU performance and near-linear scaling.
Agentic AI and Long Context
The NVIDIA Vera Rubin NVL72 is optimised for million-token context, real-time reasoning and next-generation AI agents
Flexible Scaling
Deploy single or multi-GPU configurations easily to scale workloads based on demand without committing to expensive long-term infrastructure.
NVIDIA Vera Rubin NVL72 Technical Specifications
Secure NVIDIA Vera Rubin NVL72 Capacity
Lock in NVIDIA Vera Rubin NVL72 today and power every AI workload effortlessly.
NVIDIA RTX A6000
Starting from $2.50 per hour
Power the New Era of Generative AI
Build and run real-time inference on trillion-parametre large language models. Enable faster insights, more accurate models, and more efficient operations across a variety of fields.
Transform generative AI and accelerated computing in data processing, electronic design automation, computer-aided engineering and quantum computing.
Frequently Asked Questions
We build our services around you. Our product support and product development go hand in hand to deliver you the best solutions available.
What is the NVIDIA Vera Rubin platform?
The NVIDIA Vera Rubin platform is a rack-scale AI system combining GPUs, CPUs and networking to support large-scale AI workloads.
Who should reserve NVIDIA Vera Rubin NVL72?
Teams building LLMs, agentic AI systems and large-scale inference platforms should reserve early to avoid infrastructure bottlenecks.
What is the NVIDIA Vera Rubin superchip?
The NVIDIA Vera Rubin superchip integrates compute, networking and memory into a unified AI system optimised for performance at scale.
Is NVIDIA Vera Rubin suitable for inference workloads?
Yes, the Vera Rubin NVIDIA GPU is optimised for high-throughput, low-cost inference at scale.
How do I reserve NVIDIA Vera Rubin on Hyperstack?
Submit the reservation form to reserve NVIDIA Vera Rubin, and our team will secure your capacity based on your workload requirements.
Why should I reserve NVIDIA Vera Rubinearly?
Demand for the NVIDIA Vera Rubin architecture is expected to exceed supply, so early reservations ensure guaranteed access and faster deployment.