<img alt="" src="https://secure.insightful-enterprise-intelligence.com/783141.png" style="display:none;">

NVIDIA B300s are coming to Hyperstack — On-Demand in August, reserved private clusters in Q4

alert

We’ve been made aware of a fraudulent website impersonating Hyperstack at hyperstack.my.
This domain is not affiliated with Hyperstack or NexGen Cloud.

If you’ve been approached or interacted with this site, please contact our team immediately at support@hyperstack.cloud.

close
A6000
nvidia-vera-rubin-nvl72-bm-md460-offset-left-d@2x 1
Reserve

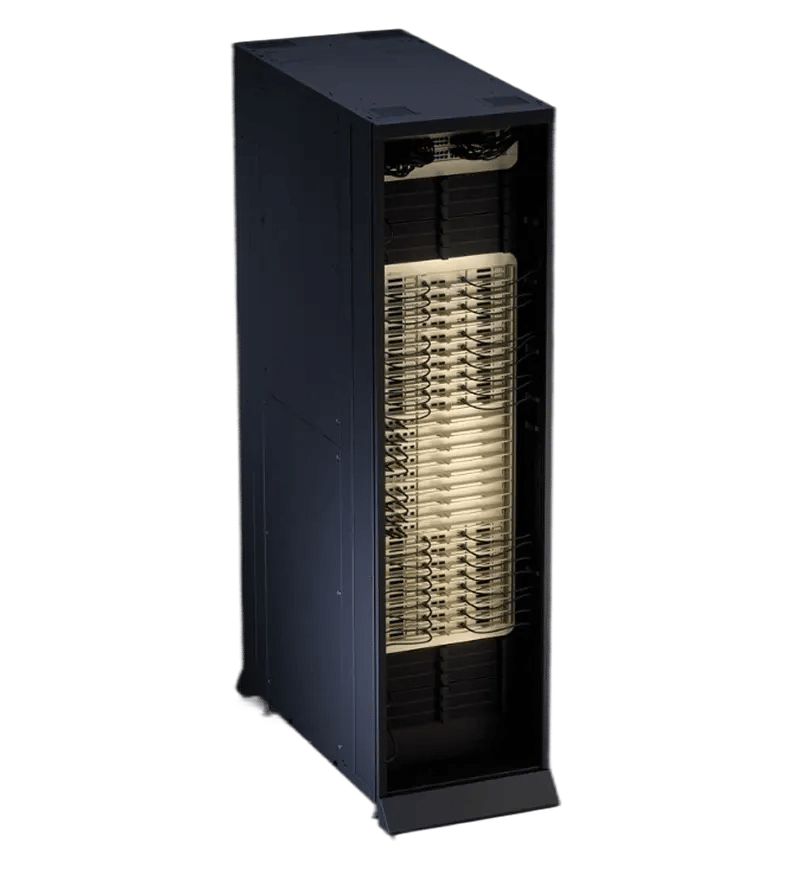
NVIDIA Vera Rubin NVL72 to Run Trillion-Parameter AI

Reserve full rack-scale NVL72 systems purpose-built for LLM training, agentic AI and ultra-high-performance inference.

product-banner-curve


tick_check

Inference Cost

1/10th cost per million tokens

tick_check

Throughput Scaling

72-GPU scale for massive models

tick_check

Compute Performance

3,600 PFLOPS NVFP4 inference

tick_check

Memory Bandwidth

1,580 TB/s bandwidth for fast data movement

What Teams Run on NVIDIA Vera Rubin NVL72

Vera Rubin NVIDIA GPU powers a new class of AI workloads:

01 . Large-Scale AI Training

Train More with Less Compute.

NVIDIA Vera Rubin NVL72 enables training with 1/4th the GPUs compared to Blackwell, so teams can scale trillion-parameter and MoE models faster while reducing infrastructure requirements.

02 . AI Inference at Scale

Serve Large Models at Lower Cost.

Deliver up to 1/10th the cost per million tokens for production-scale LLM inference, agentic systems and real-time AI applications.

03 . Agentic AI and Reasoning Systems

Run Long-context Workloads.

With support for million-token context and ultra-low latency, NVIDIA Vera Rubin NVL72 powers next-gen AI agents and autonomous systems.

04 . Data-Intensive AI Workloads

Process and Move Data at Extreme Speed.

High-bandwidth architecture across GPUs, CPUs and networking ensures seamless data flow for training, inference and large-scale AI pipelines.

Why Reserve NVIDIA Vera Rubin NVL72 on Hyperstack

cost

Next-Gen Rubin GPU Performance

Access next-gen performance from the NVIDIA Vera Rubin superchip with HBM4-powered Rubin GPUs and 50 PF NVFP4 compute for faster training, higher throughput and efficient scaling.

exceptional-ai

Purpose-Built AI CPU Architecture

Vera CPUs optimise data movement and reasoning workloads for deterministic, high-bandwidth performance in distributed AI systems and agentic applications.

icon-8

Ultra-Fast NVLink 6 Scaling

3.6 TB/s per GPU enables seamless, high-speed communication across GPUs for near-linear scaling for large distributed training and inference workloads.

high-speed-networking

High-Throughput AI Networking

ConnectX-9 SuperNIC delivers 1.6 Tb/s bandwidth with RDMA for ultra-low latency communication in large-scale and data-intensive AI clusters.

high-speed-networking

Full-Stack Infrastructure Acceleration

BlueField-4 DPUs offload networking, storage and security tasks to improve efficiency and freeing compute resources for core AI workloads.

optimised-gpu-infrastructure

Resilient, High-Efficiency Networking

Spectrum-X Ethernet delivers 5x efficiency and 10x resiliency for stable, high-performance networking in continuous AI operations at scale.

optimised-gpu-infrastructure

Breakthrough Inference Performance

Groq 3 LPUs deliver high-performance inference with 256 LPUs per rack, offering up to 35× better performance per watt and significantly higher revenue potential for trillion-parameter models.

NVIDIA Vera Rubin NVL72 Technical Specifications

nvidia-ada-lovelace

Configuration

72 NVIDIA Rubin GPUs | 36 NVIDIA Vera CPUs

nvidia-ada-lovelace

NVFP4 Inference

3,600 PFLOPS

cuda-cores

NVFP4 Training*

2,520 PFLOPS

nvidia-ada-lovelace

FP8/FP6 Training*

1,260 PFLOPS

gpu-memory

INT8*

18 POPS

memory-bandwidth

FP16/BF16*

288 PFLOPS

nvidia-ada-lovelace

TF32*

144 PFLOPS

nvidia-ada-lovelace

FP32

9,360 TFLOPS

nvidia-ada-lovelace

FP64

2,400 TFLOPS

nvidia-ada-lovelace

FP32 SGEMM*

28,800 TFLOPS

nvidia-ada-lovelace

FP64 DGEMM*

14,400 TFLOPS

nvidia-ada-lovelace

GPU Memory | Bandwidth

20.7 TB HBM4 | 1,580 TB/s

nvidia-ada-lovelace

NVLink Bandwidth

260 TB/s

nvidia-ada-lovelace

NVLink-C2C Bandwidth

65 TB/s

nvidia-ada-lovelace

CPU Core Count

3,168 custom NVIDIA Olympus cores (Arm® compatible)

nvidia-ada-lovelace

CPU Memory

54 TB LPDDR5X

Secure Your NVIDIA Vera Rubin NVL72 Capacity

The next wave of AI won’t wait and neither should your infrastructure.

Reserve NVIDIA Vera Rubin on Hyperstack to guarantee access to next-generation compute for trillion-parameter models, agentic AI and large-scale inference.
secure-nvidia-vera-rubin-nvl72-capacity

Frequently Asked Questions


What is the NVIDIA Vera Rubin platform?

The NVIDIA Vera Rubin platform is a rack-scale AI system combining GPUs, CPUs, networking and memory to power large-scale training and inference workloads.

What is the NVIDIA Vera Rubin superchip?

The NVIDIA Vera Rubin superchip integrates Rubin GPUs, Vera CPUs and high-speed interconnects into a unified system designed for extreme AI performance.

What is the Vera Rubin NVIDIA GPU used for?

NVIDIA Vera Rubin NVL72 is designed for large-scale AI workloads including LLM training, inference, agentic AI systems and high-performance data processing.

How much GPU memory does NVIDIA Vera Rubin NVL72 have?

NVIDIA Vera Rubin NVL72 features 20.7 TB of HBM4 GPU memory for training and inference of trillion-parameter models without memory bottlenecks.

What is the memory bandwidth of NVIDIA Vera Rubin NVL72?

The NVIDIA Vera Rubin NVL72 delivers up to 1,580 TB/s memory bandwidth for extremely fast data movement for large-scale AI and high-throughput workloads.

How does NVIDIA Vera Rubin NVL72 improve training efficiency?

NVIDIA Vera Rubin NVL72 can train models using up to 1/4th of the GPUs compared to Blackwell.

How can I access NVIDIA Vera Rubin NVL72 on Hyperstack?

You can reserve NVIDIA Vera Rubin NVL72 directly on Hyperstack to get guaranteed access to next-generation AI infrastructure.

What are the key NVIDIAVera Rubinspecs?

The NVIDIA Vera Rubinspecs include 72 GPUs, 20.7 TB HBM4 memory, 1,580 TB/s bandwidth and up to 3,600 PFLOPS NVFP4 inference performance.